|
Hong-Phuc Lai I'm a Research Engineer at VinMotion, working on Vision-Language-Action and World Action Models. Previously, I was a Predoctoral Research Resident at VinAI Research – Qualcomm AI Research in Hanoi, Vietnam, supervised by Principal Scientist Dr. Anh Tran, where I focused on making large generative models efficient and practical, with interests spanning Diffusion Models, Flow Matching, and Reinforcement Learning. I received my B.Sc. in Automation Control Engineering from Hanoi University of Science and Technology (HUST). |
|
ResearchI currently work on Vision-Language-Action and World Action Models. Previously, I focused on making generative models efficient, robust, and practical under real-world constraints, at the intersection of Diffusion Models, Flow Matching, and Reinforcement Learning — with a recurring focus on identifying the true bottleneck in a generative pipeline and designing lightweight algorithms to address it. Some papers are highlighted. |
|
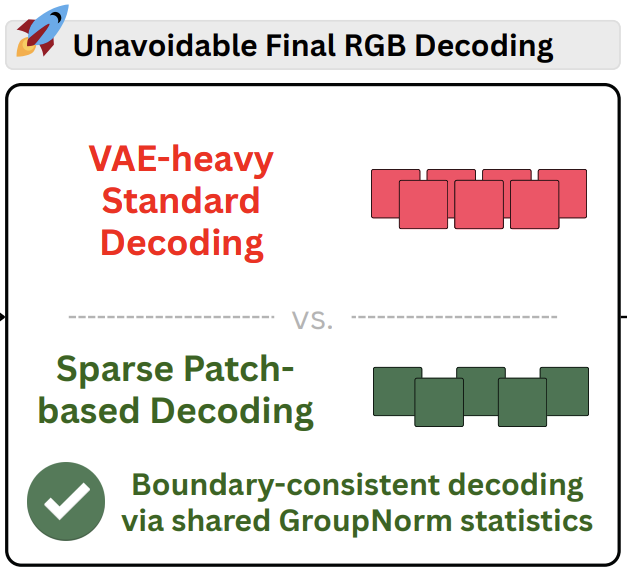
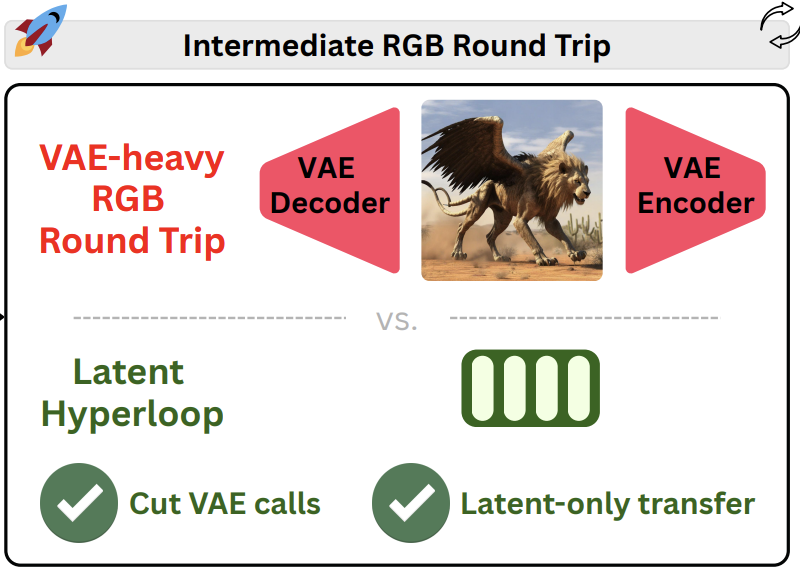
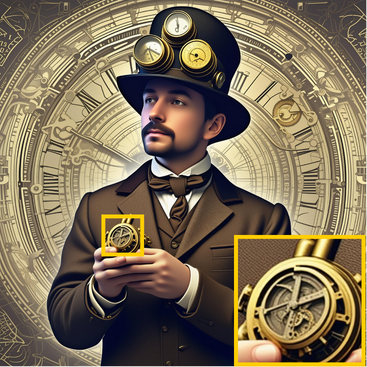
UltraFlash: Accelerating Megapixel Visual Synthesis
Hong-Phuc Lai*, Anh Nguyen*, Phong Nguyen, Anh Tran *Co-first authors NeurIPS, 2026 Addresses the VAE decoding bottleneck in high-resolution image generation, enabling further speed improvements beyond PixelRush. It speeds up megapixel synthesis beyond the denoiser, delivering ~2× faster 4K generation with better image quality than a state-of-the-art pipeline. |
|
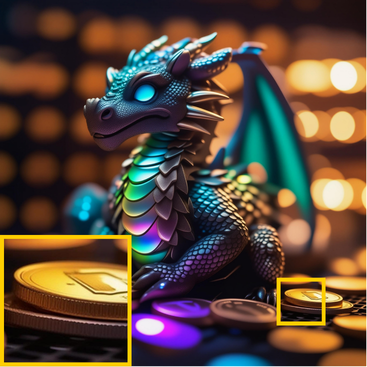
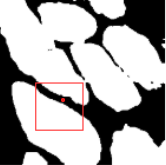
PixelRush: Ultra-Fast, Training-Free High-Resolution
Image Generation via One-step Diffusion
Hong-Phuc Lai, Phong Nguyen, Anh Tran CVPR, 2026 (Highlight) arXiv / project page / poster An ultra-fast, training-free method for high-resolution image generation via one-step diffusion, achieving state-of-the-art quality at up to 30× faster speed than prior work. |
|
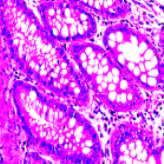
PASPP Medical Transformer for Medical Image
Segmentation
Hong-Phuc Lai, Thi-Thao Tran, Van-Truong Pham ICDSA, 2023 (Best Paper Award) paper A hybrid transformer combining pyramid spatial pooling with spatial attention for accurate medical image segmentation. |
Preprints |
|
Under
Review |
The Next Step in 3D Generation Post-Training
Cao Duy, Hong-Phuc Lai*, Anh Tran, Phong Nguyen *Co-first authors Under review Next3DGen is a unified post-training framework for text- and image-conditioned 3D generation, spanning single-stage and multi-stage models. It improves quality, condition alignment, and 3D consistency over pretrained models and substantially outperforms existing post-training methods while remaining training-efficient. |
|
SwiftAlign: Post-Distillation Alignment for Fast Flow
Models
Hong-Phuc Lai*, Anh Nguyen*, Manh Tran, Phong Nguyen, Anh Tran *Co-first authors Under review Black-box reward post-training for already-distilled few-step flow models. SwiftAlign adapts a deployed sampler to new rewards without reward gradients or a new distillation run, while keeping the deterministic ODE path used at inference. |
WritingShort notes on research. Full list on the blog.
Post-Training After the Model Is Already Fast
The Bottleneck Moves Past the Denoiser
|
|
Template from Jon Barron's website. |